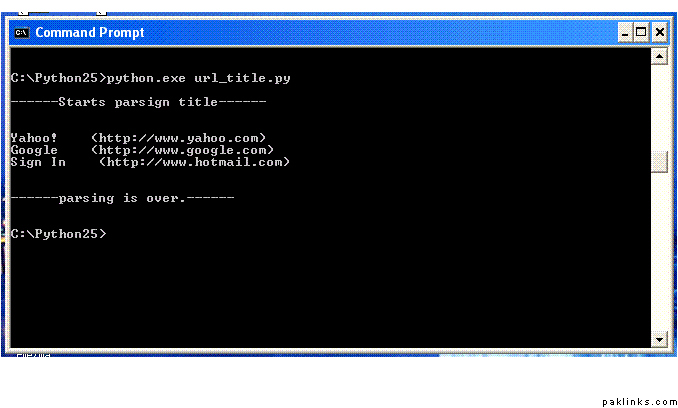
I urgently need a script that can run through a text file of URLs and traverse the links and generate each link’s respective page title.
So given a list of URLs as input, I need to get a list of webpage titles as the output.
Has anybody seen such a script or written one? I can write one myself but the need is rather urgent and thought I’d ask around first than spend a few hours on my own to write something.
Anyway, i have modified my parser script to do just the “titles” … i mean the title tag. It just parses simple string, not any special characters that may appear in the title. Those could be parsed as well; let me know if u face such titles.
ah!, just noticed that vBulletin (gs) has removed all indentation of the script. Since python does not use {} for block code, it only relies on tabbed spaces. But as u see every statement in alligned to the left-most column, so it won’t run like that. If u want to run it, i will have to send the file prob. through email.
And i missed the point that you want to read URLs from a text file, so i have modified code and have also made it to dump the results into another text file as well.
Following is the change; + shows the added code, and dots are everything same as above.